Gaurav Khanal
  • Home
  • Blog
  • Series
  • Projects
  • Notes
  • CV
  • About
Categories
All (4)
Benamou-Brenier (1)
Bregman divergence (1)
Brenier Theorem (1)
diffusion models (1)
entropic optimal transport (1)
fisher information (1)
information geometry (2)
KL divergence (1)
Natural Geometry of Learning (4)
Optimal Transport (1)
Otto's Calculus (1)
pullback metric (1)
riemannian metric (1)
Schrödinger bridge (2)
Sinkhorn (1)
stochastic optimal transport (1)
variational inference (1)
Wasserstein Distance (1)

Blog

Essays, notes, and technical writing.

Essays, notes, and technical writing on mathematics, machine learning, information geometry, and related topics.

Featured series: The Natural Geometry of Learning
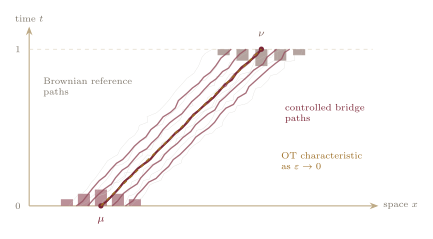
Brownian reference paths and controlled Schrödinger bridge paths between two probability distributions

The Bridge

How entropy turns transport into stochastic inference
Natural Geometry of Learning
Schrödinger bridge
stochastic optimal transport
entropic optimal transport
Sinkhorn
diffusion models
This post develops the Schrödinger bridge as the least-surprising stochastic evolution between two distributions. We will connect path-space KL to optimal transport, derive the bridge drift through its two-sided potential transform, recover Sinkhorn as alternating KL projection, and prepare the way for Hodge decomposition.

Oct 19, 2026
Gaurav Khanal
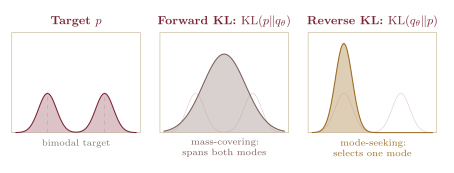
Forward and reverse KL approximations of a bimodal probability distribution

The Asymmetry of Information

Why KL divergence remembers direction
Natural Geometry of Learning
KL divergence
information geometry
Bregman divergence
variational inference
Schrödinger bridge

This post examines KL divergence as a directed contrast rather than a defective distance. We will see how its two directions shape learning, how Fisher geometry reappears as its local second-order shadow, how exponential families reveal its Bregman structure, and why path-space KL leads naturally to the Schrödinger bridge.

Aug 22, 2026
Gaurav Khanal

Diagram comparing a Kantorovich transport plan with many faint mass-splitting connections to a Brenier deterministic map with one arrow from each source bin to a target bin.

The Second Ruler of Displacement

Why Wasserstein distance is the geometry of moving probability mass
Natural Geometry of Learning
Optimal Transport
Wasserstein Distance
Brenier Theorem
Benamou-Brenier
Otto's Calculus

This post introduces Wasserstein distance as the second “ruler” for probability distributions: a metric that measures the cost of moving probability mass through space. We will see why it arises from the Earth Mover’s problem, why the quadratic case has special geometric structure through Brenier’s theorem, and how the Benamou–Brenier formulation turns optimal transport into a dynamic geometry of probability flows.

Jun 13, 2026
Gaurav Khanal

Diagram showing parameter space mapping into distribution space, with tangent vectors represented logarithmically as score functions and the Fisher metric obtained as a pullback.

The First Ruler of Distinguishability

Why Fisher information is the local geometry of statistical models
Natural Geometry of Learning
information geometry
fisher information
pullback metric
riemannian metric

This post introduces Fisher information as the first “ruler” for probability distributions: a local metric that measures how distinguishable nearby statistical models are from data. We will see why it arises naturally as a pullback metric, why Chentsov’s theorem makes it unique, and how it foreshadows the deeper connection between KL divergence, natural gradients, and learning.

Jun 5, 2026
Gaurav Khanal
No matching items

© 2026 Gaurav Khanal

Mathematics · Machine Learning · Geometry

  • View source
  • Report an issue